
Accelerate DML with Comm Schedule
Overview
At present, communication overhead has become the bottleneck of distributed machine learning(DML) training. DML usually adopts a centralized parameter server(PS) architecture, which easily leads to unreasonable utilization of network resources.
We design a network priority scheduling method to accelerate distributed machine learning by analyzing lots of communication track of DML based on PS.Through experiments, DML with priority scheduling was accelerated by 30% on average.
Experiment Topology
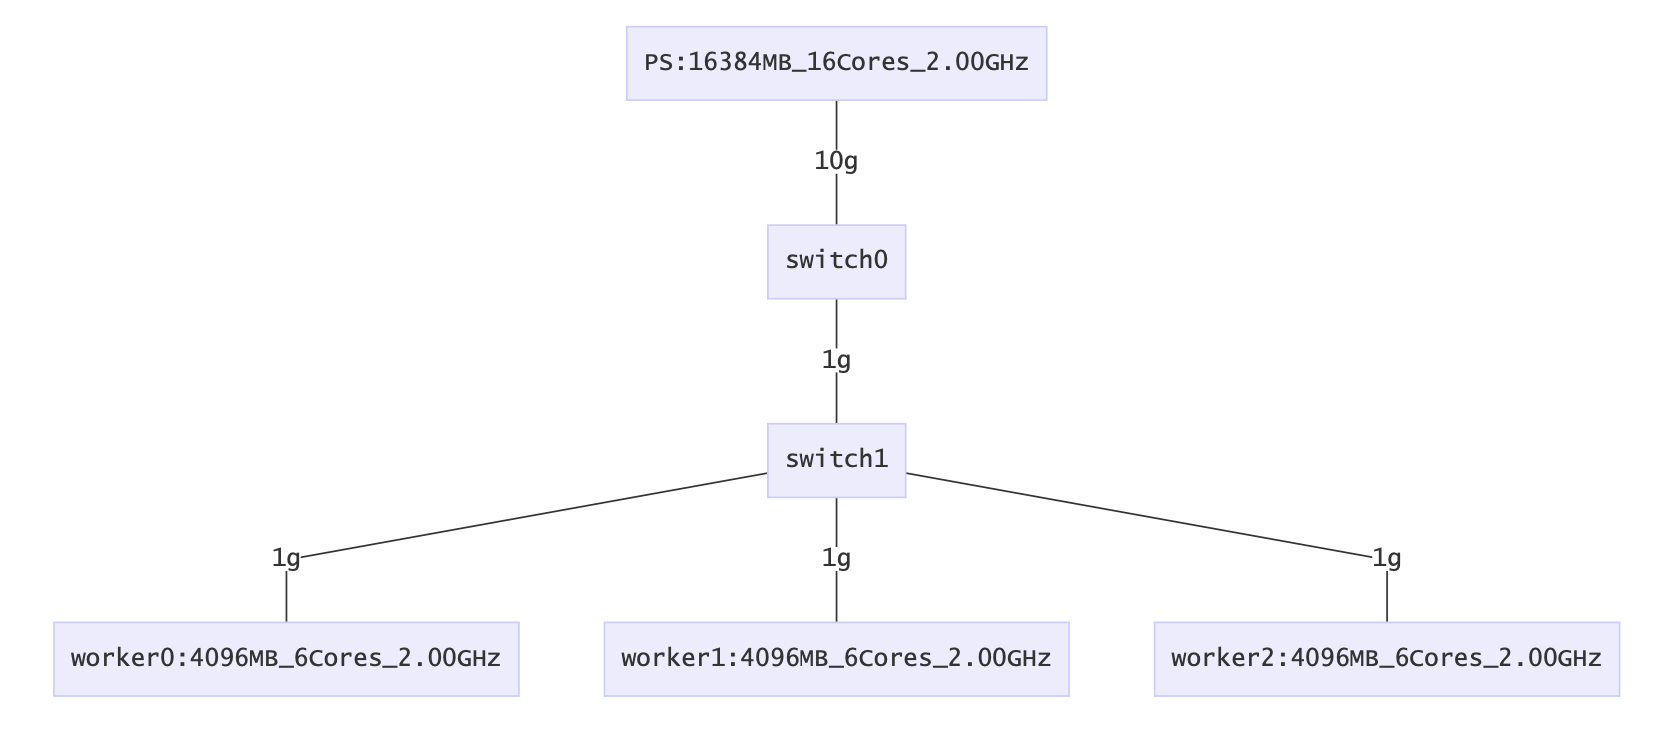
Due to the current technical limitations of the implementation, scheduling is only effective through the switch, so there are seemingly superfluous 10g links and switch1 above. We are actively looking for ways to implement scheduling on the host.
Current Results
| model | param mem | flops | no schedule(imgs/sec) | with schedule(imgs/sec) | speed up |
|---|---|---|---|---|---|
| alexnet | 233 MB | 727 MFLOPs | 0.24 | 0.34 | 41.67% |
| googlenet | 51 MB | 2 GFLOPS | 2.06+2.11+2.14+ 2.22+2.15=2.136 | 2.66+2.84+2.78+ 2.87+2.84=2.798 | 30.99% |
| inception3 | 91 MB | 6 GFLOPS | 0.63+0.62+0.62+ 0.64+0.63=0.628 | 0.79+0.78+0.79+ 0.83+0.75=0.788 | 25.48% |
| resnet50 | 107 MB | 4 GFLOPS | 0.6+0.6+0.59+ 0.6+0.58=0.594 | 0.78+0.78+0.76+ 0.76+0.77=0.77 | 29.63% |